Tuesday, 14 June 2022

Save dataframe to table and ADLS path in one go

 Lets see how to save dataframe into a table and create view on adls.


df.write.format('delta')
            .mode('overwrite')
            .option('overwriteSchema', 'true')
            .saveAsTable('{database_name}.{tbl}'.format(database_name = database,tbl = table_name)
                , path = '{base_dir}/{tbl}/'.format(base_dir  =  location,tbl  =  table_name))

How to get Azure Key Vault values into Azure Databricks Notebook

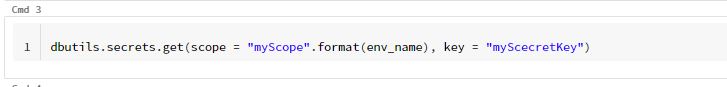
It is always a best practice to store the secrets in Azure Key vault. In order to access them in databricks , first a scope needs to be defined and using the scope and key you will be able to access the secrets.


In below example scope is "myScopeDEV" and key is "myScecretKey". Passing env_name as "DEV"


Saturday, 17 April 2021

How to calculate rolling dates using pySpark

Lets ​calculate current year minus 3 years data using pySpark 
  
You can achieve this using F.add_months(current_date(),-36) option


You also have the option to change the dates/year to start . In order to achieve this use ​F.trunc("end_date", "month") and F.trunc("end_date", "year") 


Monday, 5 October 2020

How to write dataframe output to a single file with a specific name using Spark


Spark is designed to write out multiple files in parallel. So there may be cases where we need to merge all the part files, remove the success/commit files and write the content to a single file.

This blog helps you to write spark output to a single file.

Using  df.coalesce(1) we can write data to a single file, 

 result_location = "dbfs:///mnt/datalake/unmesha/output/"   df.coalesce(1).write.format("csv").options(header='true').mode("overwrite").save(result_location)

but still you will see _success files.


This solution - adding coalesce isn’t sufficient when you want to write data to a file with a specific name.

We are going to achieve this using dbutils
  result_location = "dbfs:///mnt/datalake/unmesha/output/"
     df.coalesce(1).write.format("csv").options(header='true').mode("overwrite").save(result_location)
  files = dbutils.fs.ls(result_location)
  csv_file = [x.path for x in files if x.path.endswith(".csv")][0] 
  dbutils.fs.mv(csv_file, result_location.rstrip('/') + ".csv") 
  dbutils.fs.rm(result_location, recurse = True)
 Above snippet helps you  to write dataframe output to a single file with a specific name.


How to append content to a DBFS file using python spark


You can read and write to DBFS files using 'dbutils'

Lets see one example

dbutils.fs.put("dbfs:///mnt/sample.txt", "sample content")

Above command helps to write "sample content" to 'dbfs:///mnt/sample.txt'

Now you have the file in your DBFS location. Lets see how to append content to this file.


In order to do that, you can open the file in append mode.


with  open("/dbfs/mnt/sample.txt", "a") as f:
  f.write("append values")

Now your appended file is ready!!!


How to access data in Delta tables


Delta tables can be accessed either by specifying the path on DBFS or by table name.

You can check my previous blog to see how to write delta files here.  I will be using the same example location here.


Option 1 : Read delta tables by specifying DBFS path

val employeeDF = spark.read.format("delta").load("/mnt/delta/Employee")


Option 2 : Read delta table by  table name

val employeeDF = spark.table("employee")

Thursday, 24 September 2020

Create Delta table on csv file in python spark


You can read files into Dataframe and write out in delta format

Step 1 : Read the input csv

Step 2 : Write the csv to ADLS location using Delta format

Step 3: Create a table on top of it


myCSV= spark.read.csv("/path/to/input/data",header=True,sep=","); 
myCSV.write.format("delta").mode("overwrite").option('overwriteSchema','true').save("/mnt/delta/Employee") 
spark.sql("CREATE TABLE employee USING DELTA LOCATION '/mnt/delta/Employee/'")